Research preprint
 Research grade intelligence
Confidence, built on evidence.
Independent, research-backed evaluation for AI used in consequential work.
Built around your model, your use case, and the decision you need to stand behind.
Research findings and perspectives on how AI learns, reasons and fails.
Every investigation starts with the work your AI needs to do. We design the tests around your system, industry and operating conditions.
Buying a company, developing a model, choosing a system or investigating a failure. We shape the evaluation around what you need to know.
Independent evidence for an acquisition or investment decision.
Put your model's capabilities and claims to the test.
Find the right model for your tasks, constraints and budget.
Understand where a model fails and what needs closer scrutiny.
Your systemYour use caseYour domain
Define the decision, domain and model access.
Build an evaluation around your real use case.
Examine behaviour, failures and their possible causes.
Explain the findings, limits and next steps.
Our research informs tailored tests and our own benchmarks. Where model access allows, we measure internal computation during training and inference to investigate behaviour beyond outputs.
An independent report connects the findings to your decision, with clear recommendations and limits on what the evidence establishes.
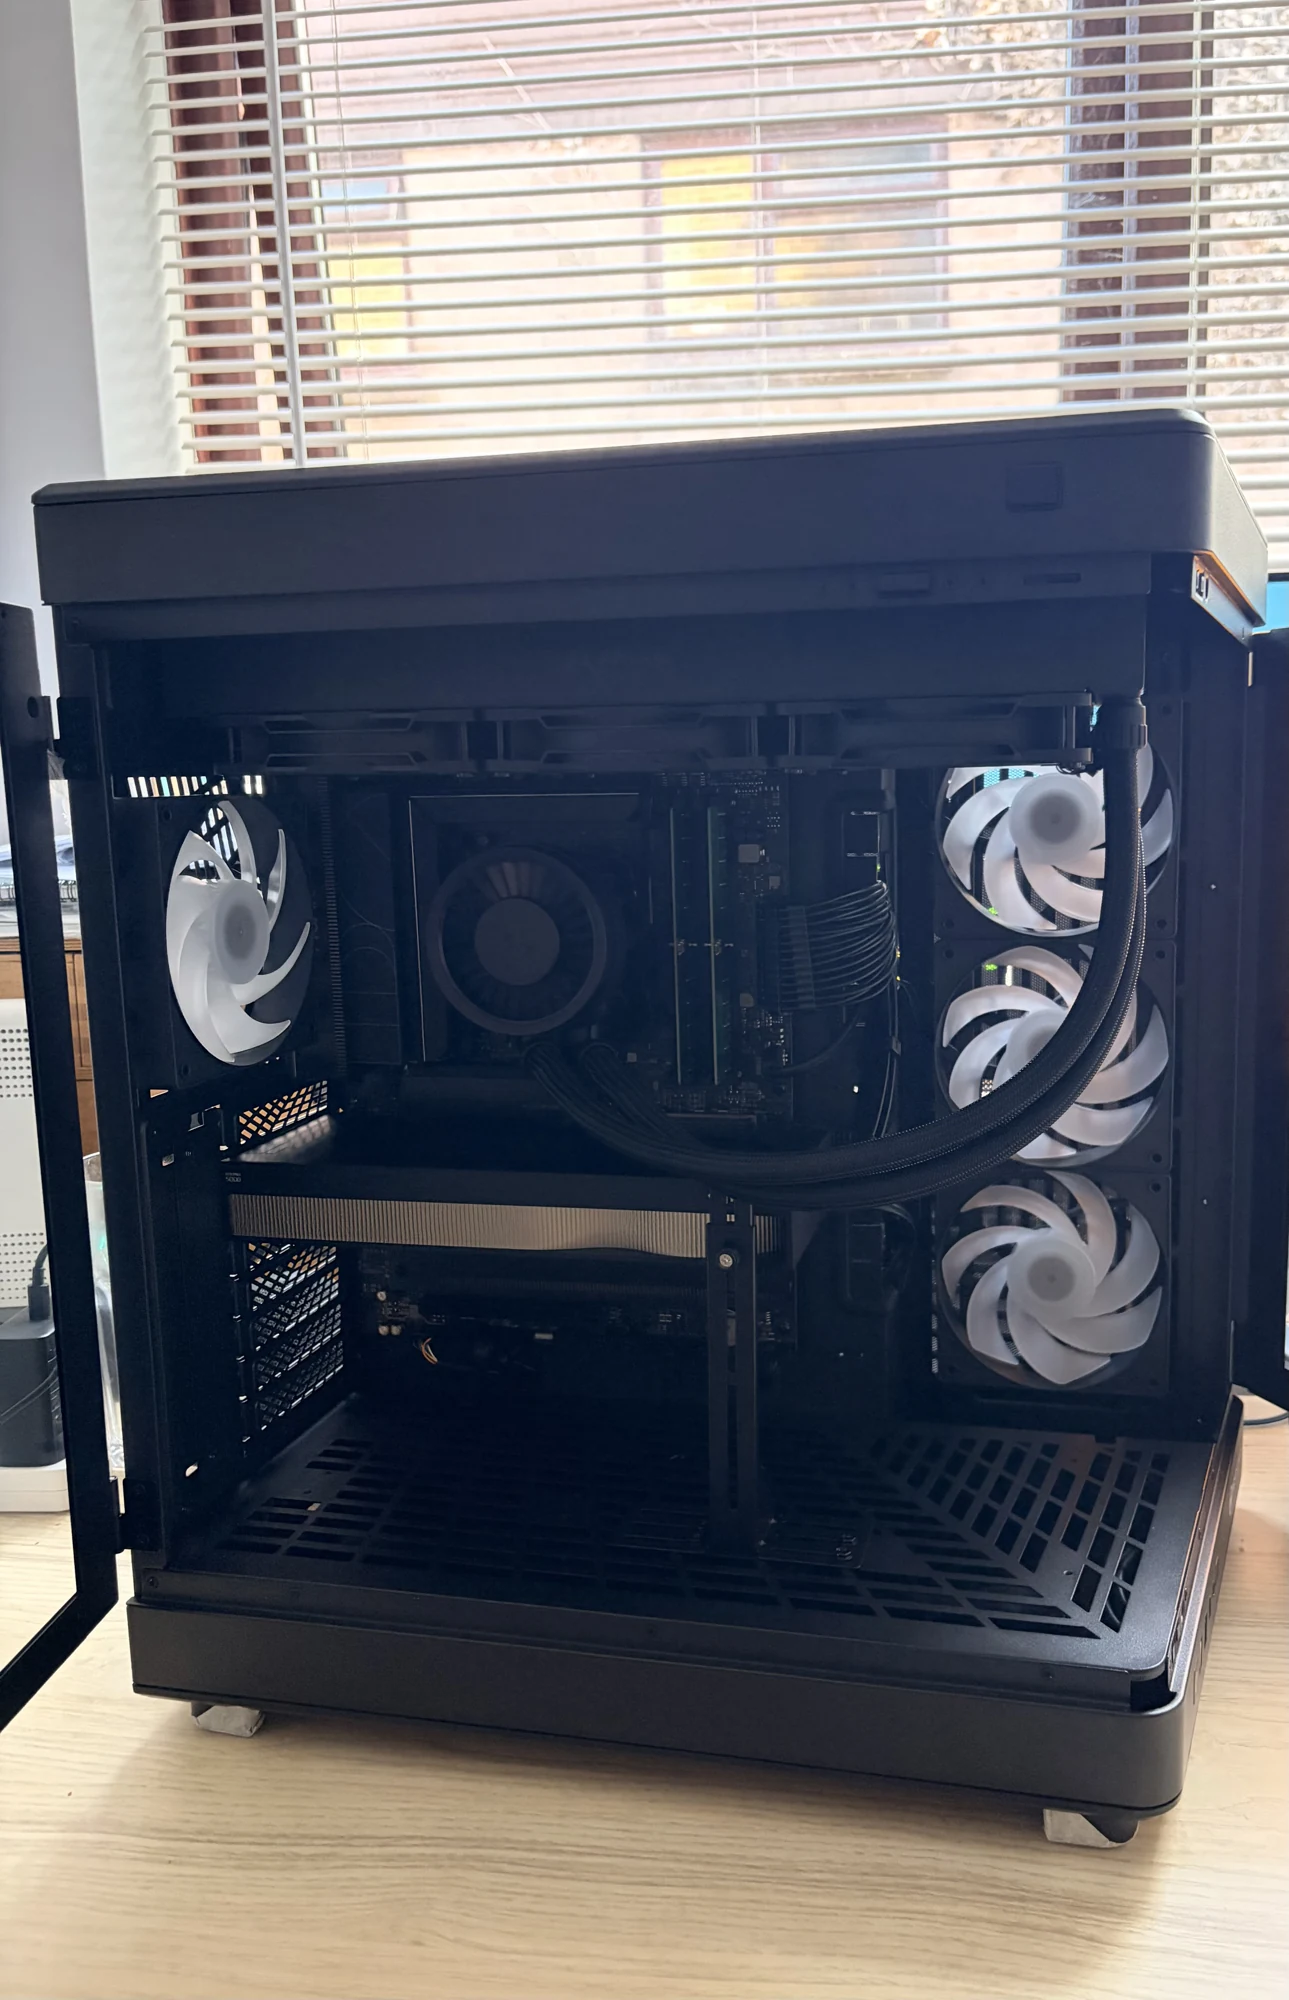
Model analysis and evaluation infrastructure.
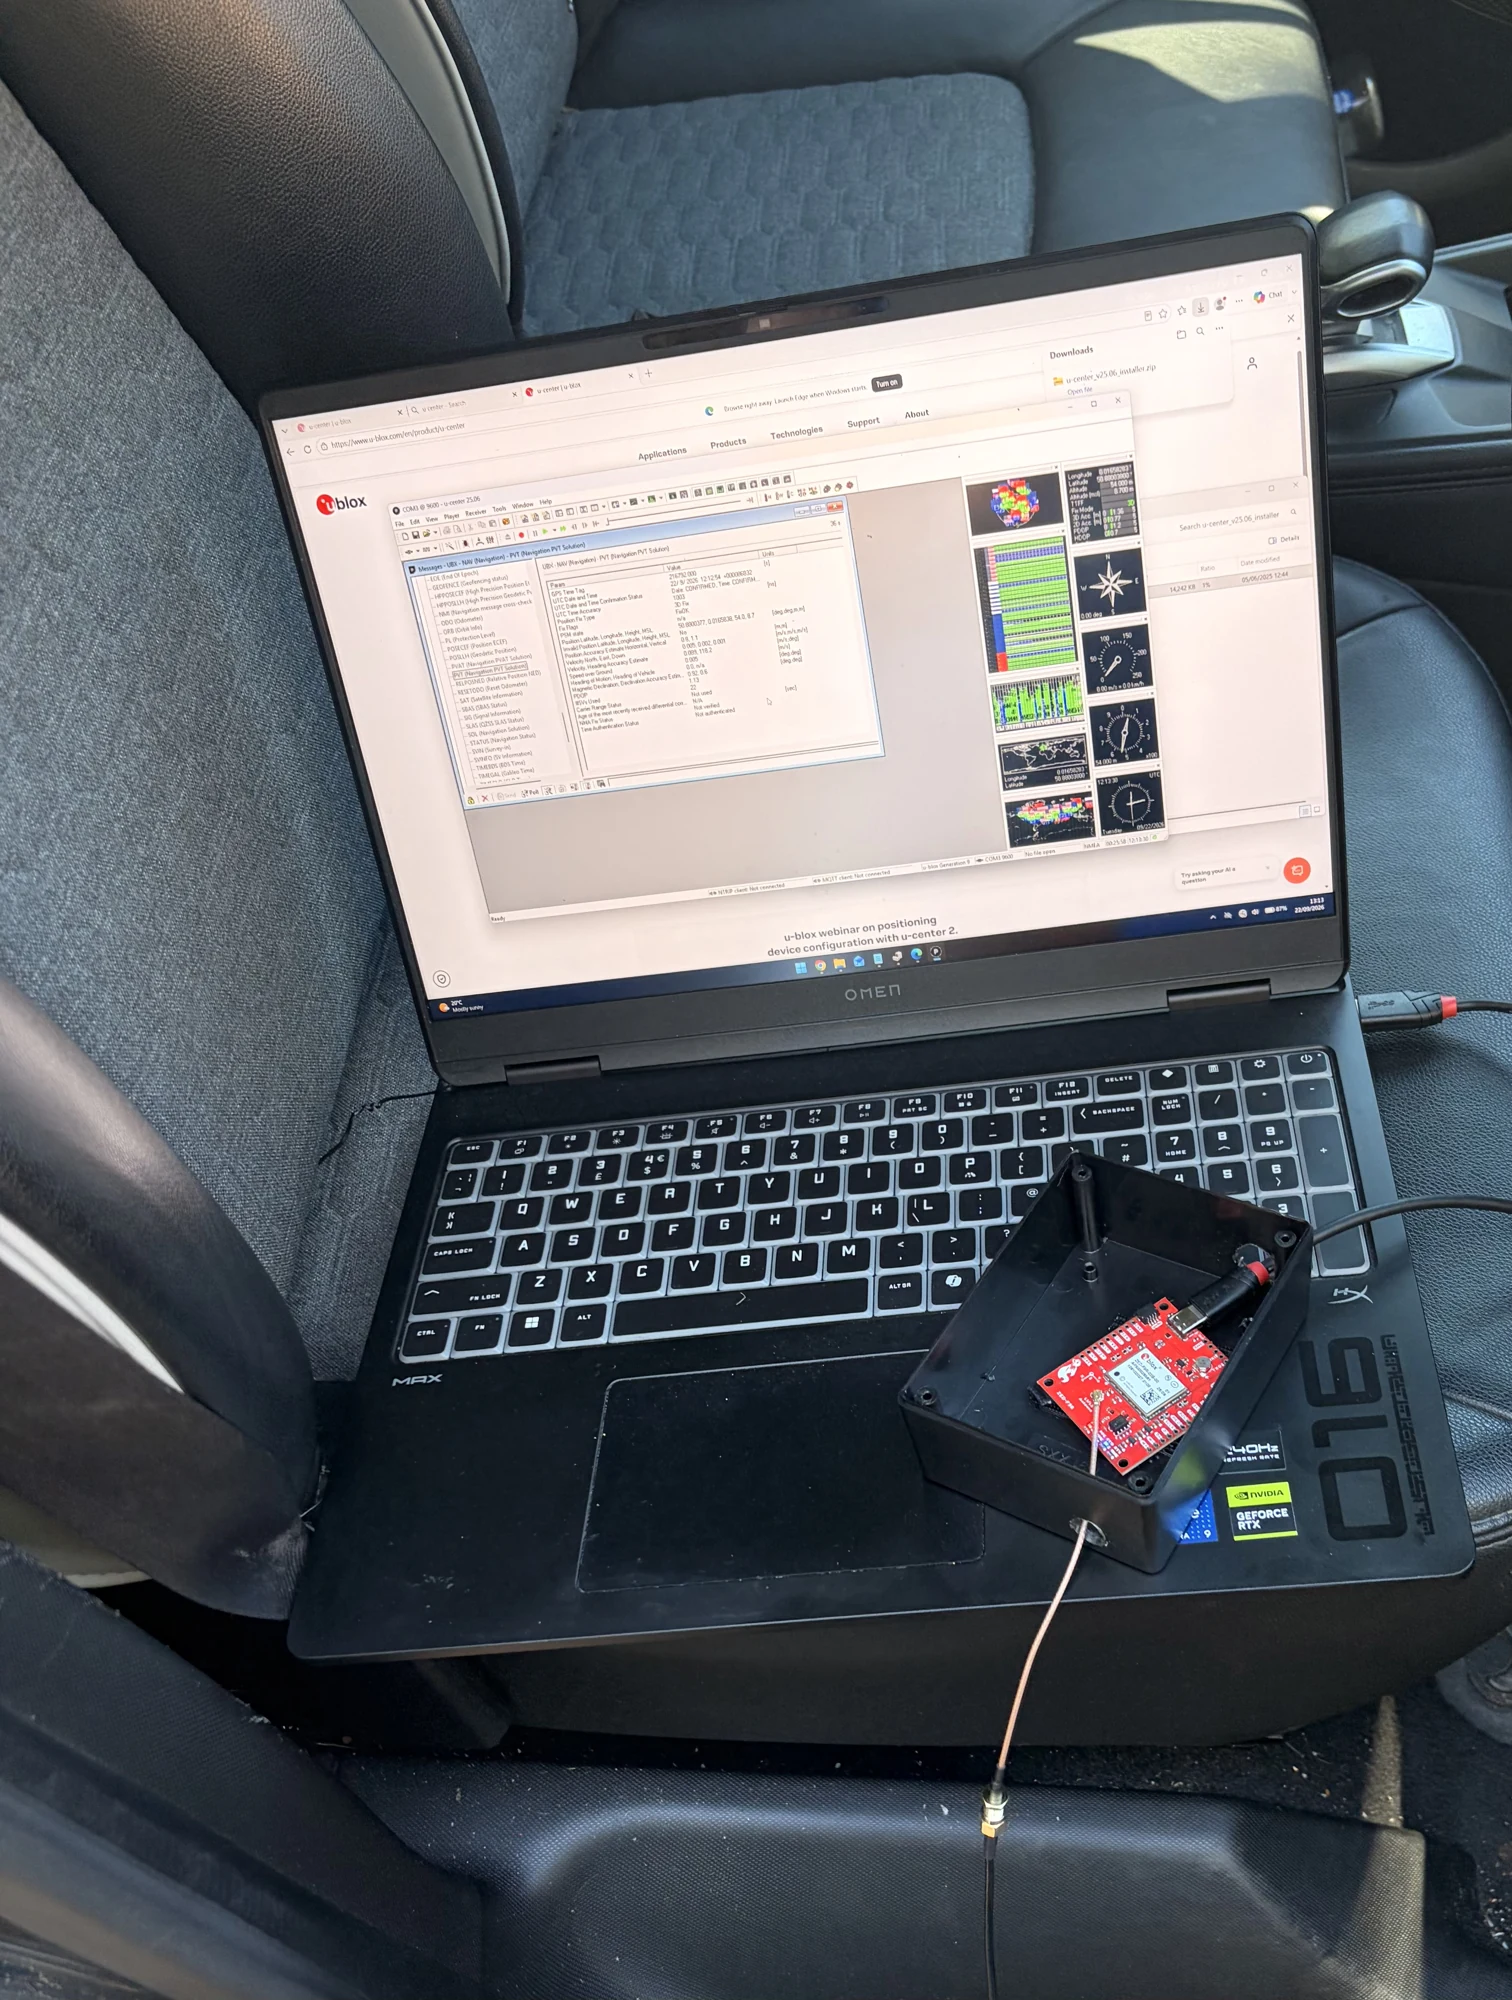
Real-world vision and sensor evaluation.
Hands-on technical R&D, from model behaviour to real deployment environments.
Discover failure modes conventional evaluation misses.
Design a bespoke investigation around your model, use case and decision.
Test specific claims and revisit performance as models and conditions change.
Our research and evaluation tools provide the foundation. Each engagement applies them to a specific system and context, producing evidence you can use and methods we can continue to develop.
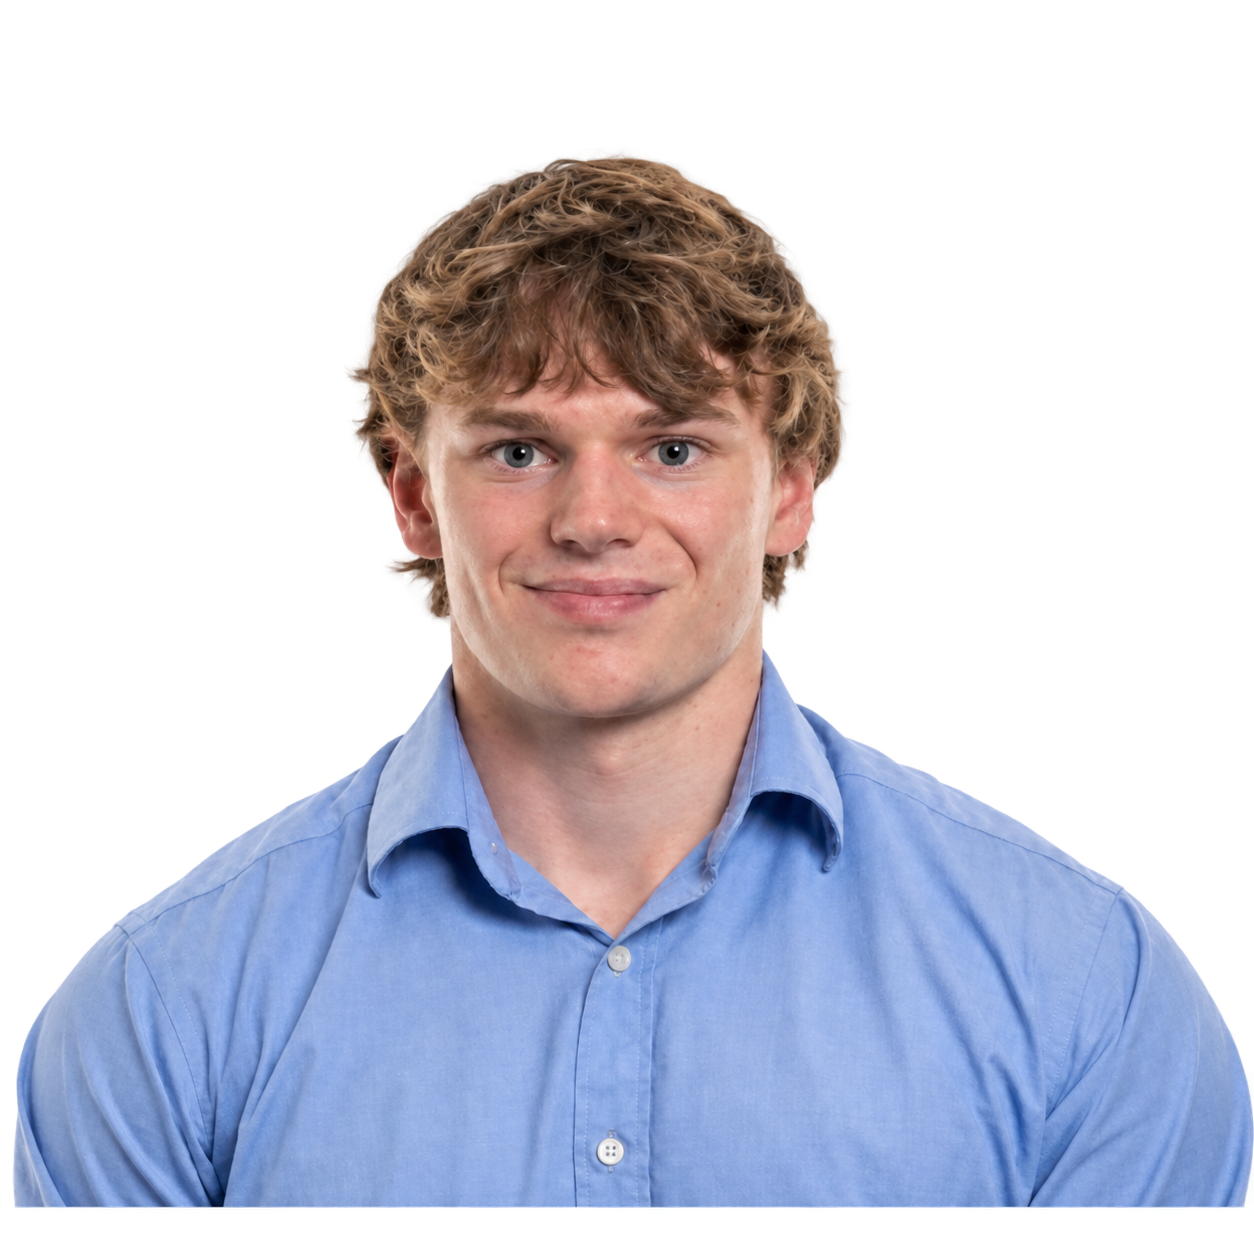
Founder, Oneirix
Research focused on failure dynamics, recurrent computation and AI assurance.
Raising pre-seed funding.
Tell us what you need to understand about your model or AI workflow. We'll shape an independent investigation around your questions.
Work with Oneirix